Category Archives: History

Surviving Quals, Part I: Laying the Groundwork

*This is part one of a series on preparing, studying for, and taking qualifying exams in a history PhD program. After taking my exams in December 2011, I decided to collect my thoughts on the process. The following advice is based on my own experience in taking Stanford’s qualifying oral exams for United States history. The format was a two-hour oral exam, with four faculty members testing four different fields: three standard American history fields (Colonial, Nineteenth Century, and Twentieth Century) and one specialty field (in my case, Spatial and Digital History). Bear in mind that other programs have different purposes, formats, and requirements.*

Laying the Groundwork (Or, Helping Your Future Self)

From a big-picture standpoint, studying for qualifying exams begins as soon as you start your graduate program. I mean this largely in a meta-sense: you should not be constantly thinking about your quals as a first-semester graduate student, but the classes you are taking, the papers you are writing, the courses you are TAing, are all building your knowledge base. On a more logistical standpoint, you should figure out the details of exams early on: what are the requirements, what the process is generally like, what the deadlines and dates are, who serves on your committee, etc. Which brings me to my first recurring theme:

Theme #1: Ask for Help

Talk to students who have already gone through or are currently going through the process. Department guidelines and handbooks are helpful, but actual students can usually tell you exactly what will happen and what you’ll need to do. Is there a department policy that is particularly onerous? Are credit requirements set in stone, or are they more flexible? Talking to students will give you a better sense for what all you need to do in a way that is often more directly relevant than talking to professors or administrators.

In the classroom, it’s crucial that you take systematic notes. This might seem straightforward. It’s not. There will be many, many weeks where you are swamped by papers, reading, or grading. These are the weeks when it’s much easier to underline and scribble just enough notes in the margin of a book to get through the day’s discussion rather than systematically writing it down. Don’t. Two years later these marginalia that made sense at the time are often barely helpful. Similarly, I’ve found that graduate seminars encourage a different kind of analysis than qualifying exams. In courses you usually talk about a book within a few days of reading it, dissect the book in a discussion setting (often with a graduate student enthusiasm for viciously ripping it apart), and then immediately setting it aside to move on to the following week’s reading. Studying for exams is much more about synthesizing and retaining massive amounts of information and big ideas. Which brings me to my second recurring theme:

Theme #2: Get Organized

Qualifying exams are often as much about persistence and organization as they are about intellectual firepower. Each person has different styles of note-taking, but for studying purposes active synthesis is absolutely crucial. To this end, I would taking 15 minutes after you’ve read and discussed a book to write up a short, 2-3 paragraph summary. I cannot over-emphasize how helpful these summaries will be – unless you are blessed with an extraordinary memory, the particulars of a book will often fade in a matter of weeks or months. Keeping the summary short forces you to consider what the major contributions and points of the book are. Take notes in class discussions about relevant context or historiography, and keep these notes alongside your summary. Your future self will thank you immeasurably.

The process of composing your reading lists will vary from program to program and professor to professor. My experience consisted of me coming up with a draft reading list for each field, submitting it to my committee member for review, and then incorporating their revisions. Regardless of the specifics, always refer to Theme #1: Ask for Help. Nobody sits down and comes up with a list from scratch. Go through as many reading lists from older graduate students as you can and you will start to get a sense for which books are part of the “canon” (for instance, Winthrop Jordan’s White Over Black was on every single list I consulted). For some reference, here were my reading lists for Colonial, Nineteenth-Century, and Twentieth-Century U.S. History.

An important note on this stage of the process: this is the fun part. If you’re in a history graduate program for the right reasons, you will be giddy thinking about all these cool books you want to read. This is wonderful, but don’t get carried away. It is easy to put every book you’ve ever wanted to read on the list. Don’t. Adding an extra book here and there seems harmless, but they add up quickly. And when you realize your exam is a month away and you’re fourteen books behind schedule you’ll be kicking yourself for adding in so many extra readings. This ties into my third theme:

Theme #3: Be Efficient 

To winnow it down, ask older graduate students about which are most valuable. Which books are particularly versatile or useful? Are there books they absolutely loved or hated? A book like Robert Self’s American Babylon allows you to answer a wide range of topics related to post-World War II America: metropolitan development, suburbanization, the rise of conservatism, race and identity politics, spatial history, and civil rights. Do you have multiple books covering the same topic? If so, which one(s) should you jettison? For instance, I included both Ira Berlin’s Many Thousands Gone and Philip Morgan’s Slave Counterpoint. Both are fantastic books, but in retrospect there was too much overlap between them. For the purpose of quals I wished I had substituted another book on colonial slavery for the seven-hundred page Slave Counterpoint that offered a much more different approach. Whenever you engage in a give-and-take with your committee member for a particular list, be firm. If you really want to include a particular book or think that the list is getting too long, lobby as strongly as you can to change it. Some professors will give you more leeway than others, but regardless do as much as you can to shape the list into what you want it to be. Which is all a part of my fourth theme:

Theme #4: Own It

Graduate students are endlessly warned about choosing a dissertation topic that they truly love. The same advice should be applied to reading for quals. Take the time to really think about what you want to get out of the entire experience. Figure out what the purpose is supposed to be. Stanford’s process is geared much more broadly towards preparing its graduate students to teach American history. Other programs aim to give you a mastery of the literature related more narrowly to your research agenda. Whatever the purpose, think long and hard about what specifically you want to emerge with. This can be as broad as “designing a survey course on colonial America” or as narrow as “finally understanding the Progressive Era.” Quals are an often-onerous academic hoop for you to jump through, so you might as well try to make it as valuable and enjoyable a hoop as you can.

On Lecturing

The life of a history graduate student is remarkably short on excitement. Nicholas Cage might break into the National Archives and steal the Declaration of Independence in order to find a hidden treasure buried by the founding fathers, but the rest of us spend most of our time reading piles of really long books. We also talk about those books. And write papers about them. I love what I do, but there are few moments of my work that I would classify as thrilling. Standing in front of a classroom of sixty undergraduates, about to deliver my own lecture for the very first time, however, was a moment that I would put in the “thrilling” category.

Over the past three months I was a teaching assistant for History 150A: Colonial and Revolutionary America, taught by Professor Caroline Winterer. The TAs were given the option of lecturing on a topic of our choosing for half of a class period. So on a Tuesday morning in November I found myself death-gripping the sides of a podium and trying to ignore the fact that I had about a hundred eyes staring at me. The next half hour was largely a blur, but fortunately Stanford’s Center for Teaching and Learning provides a wonderful service for professors, lecturers, and teaching assistants: they will come to your classroom and videotape a class period. So, in what seems appropriate for someone who studies the practice of history in a digital age, the very first lecture of my academic career was captured on video.

Lecturing, and public speaking more generally, is a curiously under-trained aspect of graduate school. I’ve received detailed and continuous feedback over the past year-and-a-half on my historical writing. Yet as graduate students we rarely receive feedback on another fundamental component of being an historian: verbal communication. Especially for the majority of us who will be teaching for the rest of our careers, effectively conveying concepts to a roomful of people is absolutely crucial. This is why I appreciate CTL’s videotaping service so much, and why I have been encouraging everyone I know to take advantage of it. Especially for those of us (like myself) without much experience delivering lectures, they provide a high-quality means of self-assessment.

Do I talk too fast? Too softly? Are my gestures distracting? Do I really say “you know” at the end of every sentence? These are the kinds of questions that often float beneath the radar of our own self-perceptions, but whose answers become immediately apparent when watching a video of yourself lecturing. Beyond noticing verbal patterns, re-watching a lecture allows you to gauge how well the written structure translated into a spoken one. This was one of the more illuminating parts of my own self-evaluation. Some of the examples that I had tried to emphasize in my lecture notes fell flat when I said them out loud. Other points that I had considered secondary came off sounding much more emphatic. An analytical thread that you can easily follow while reading a paragraph sometimes gets lost after two sentences in a lecture. Studying the delivery of a lecture with a knowledge of how it was written drives home the point that building a paper and building a lecture require two related, but fundamentally different, styles of writing.

While videotaped self-assessment can be quite valuable, I quickly realized its limitations in answering the most important questions in evaluating a lecture. How much of it did the students really “get”? Did they actually understand the themes I was trying to describe and the argument I was trying to make? How many remember any of its details a month later? These, of course, are the kinds of pedagogical questions that are notoriously difficult to answer and certainly outside the realm of a thirty-minute video. Regardless, I found delivering a lecture to a roomful of students to be incredibly valuable, and while it wasn’t quite as exciting as stealing the Declaration of Independence, it was a thrilling experience.


Digital Humanities Labs and Undergraduate Education

Over the past few months I was lucky enough to do research in Stanford’s Spatial History Lab. Founded three years ago through funding from the Andrew Mellon Foundation, the lab was grown into a multi-faceted space for conducting different projects and initiatives dealing with spatial history. Having worked in the lab as a graduate affiliate over the past nine months as well, I can attest to what a fantastic environment it provides: computers, a range of software, wonderful staff, and an overarching collaborative setting. There are currently 6-8 ongoing projects in various stages at the lab under the direction of faculty and advanced graduate students, which focus on areas ranging from Brazil to Chile to the American West. Over ten weeks this summer, eight undergraduate research assistants worked under these projects. I had the opportunity to work alongside them from start to finish, and came away fully convinced of the potential for this kind of lab setting in furthering undergraduate humanities education.

The eight students ranged from freshman to the recently-graduated, who majored in everything from history to environmental studies to computer science. Some entered the program with technical experience of ArcGIS software; others had none. Each of them worked under an existing project and were expected to both perform traditional RA duties for the project’s director and also develop their own research agenda for the summer. Under this second track, they worked towards the end goal of producing an online publication for the website based on their own original research. Led by a carefully-planned curriculum, they each selected a topic within the first few weeks, conducted research during the bulk of the summer, went through a draft phase followed by a peer-review process, and rolled out a final publication and accompanying visualizations by the end of the ten weeks. Although not all of them reached the final point of publication at the end of that time, by the final tenth week each of them had produced a coherent historical argument or theme (which is often more than I can say about my own work).

The results were quite impressive, especially given the short time frame. For instance, rising fourth-year Michael DeGroot documented and analyzed the shifting national borders in Europe during World War II. Part of his analysis included a dynamic visualization that allows the reader to see major territorial changes between 1938-1945. DeGroot concludes that one major consequence of all of these shifts was the creation of a broadly ethnically homogenous states. In “Wildlife, Neoliberalism, and the Pursuit of Happiness,” Julio Mojica, a rising junior majoring in Anthropology and Science, Technology, and Society, analyzed survey data from the late twentieth-century on the island of Chiloé in order to examine links between low civic participation and environmental degradation. Mojica concludes that reliance on the booming salmon industry resulted in greater tolerance for pollution, a pattern that manifested itself more strongly in urban areas. As a final example, senior history major Cameron Ormsby studied late-19th century land speculation in Fresno County and impressively waded into a historiographical debate over the issue. Instead of speculators serving as necessary “middle-men” between small farmers and the state, Ormsby convincingly argues that they in fact handicapped the development of rural communities.

The success of the summer program speaks not only to the enthusiasm and quality of Stanford undergraduates, but more centrally to the direction of the lab and it’s overall working environment. By fostering an attitude of exploration, creativity, and collaboration, the students were not only encouraged, but expected to participate in projects as intellectual peers. The dynamic in the lab was not a traditional one of a faculty member dictating the agenda for the RA’s. In many cases, the students had far greater technical skills and knew more about their specific subjects than the project instructor. The program was structured to give the student’s flexibility and freedom to develop their own ideas, which placed the onus on them to take a personal stake in the wider projects. In doing so, they were exposed to the joys, challenges, and nitty-gritty details of digital humanities research: false starts and dead-ends were just as important as the pivotal, rewarding “aha!” moments that come with any project. Thinking back on internships or research assistant positions, it’s difficult for me to imagine another undergraduate setting that would encourage this kind of wonderfully productive hand-dirtying process. And while I think digital humanities labs hold great potential for advancing humanities scholarship, I have grown more and more convinced that some of their greatest potential lies in the realm of pedagogy.

Getting Under the Hood of Graduate Coursework

As part of Stanford’s history graduate program, those of us studying the United States participate in a series of courses called “the core.” This consists of six courses taught by six different professors that cover the chronology of the United States – two each for (roughly) the eighteenth, nineteenth, and twentieth centuries. On Stanford’s quarter system, this works out to three “core” classes each year that comprise the backbone of the Americanist graduate training. Having completed half of the core, I thought it would be interesting to take a look at its content.

Each course follows a similar format: one book assigned each week, usually accompanied by additional excerpts or chapters of other books and related essays. The class posted short responses/questions which we then discussed in our once-weekly class. Even with a small class (around 8-12 students), the aggregate of our short responses produced a sizable body of text over the course of the year. The responses also offer a means of gleaning some of the overarching themes of US historiography. As Julie Meloni describes in a post at ProfHacker titled “Wordles, or the gateway drug to textual analysis” word clouds are an easy and playful way to visualize these themes:

Many of the words are not particularly surprising (American, history, and book, for example), but the word cloud does point towards the essence of Stanford’s “core” in training its graduate students to analyze texts from a largely historiographical standpoint. There are relatively few content words  – Vietnam doesn’t appear too often, for instance. Instead, words such as analysis, argument, and narrative crop up in our responses. We are being trained to read a book not for its factual information but in order to evaluate its interpretive arguments. This is a crucial difference that often gets overlooked by those outside the profession, and this characteristic displays itself quite clearly in our responses.

Examining the central books that were assigned in the core gives a glimpse into what our professors thought were the important works in United States historiography. What follows are the major weekly books, in order of publication date:

Patricia Limerick The Legacy of Conquest: The Unbroken Past of the American West
Gordon Wood Radicalism of the American Revolution
Charles Sellers The Market Revolution: Jacksonian America, 1815-1846
William Cronon Nature’s Metropolis: Chicago and the Great West
Richard Bushman The Refinement of America: Persons, Houses, Cities
Robin Kelley Race Rebels : Culture, Politics, and the Black Working Class
Christine Leigh Heyrman Southern Cross: The Beginnings of the Bible Belt
Amy Dru Stanley From Bondage to Contract: Wage Labor, Marriage, and the Market in the Age of Slave Emancipation
Kristin Hoganson Fighting for American Manhood: How Gender Politics Provoked the Spanish-American and Philippine-American Wars
Walter Johnson Soul by Soul: Life Inside the Antebellum Slave Market
Ann Fabian The Unvarnished Truth: Personal Narratives in Nineteenth-Century America
Mary Dudziak Cold War Civil Rights: Race and the Image of American Democracy
Elizabeth Anne Fenn Pox Americana: The Great Smallpox Epidemic of 1775-82
Sven Beckert The Monied Metropolis: New York City and the Consolidation of the American Bourgeoisie, 1850-1896
Caroline Winterer The Culture of Classicism: Ancient Greece and Rome in American Intellectual Life, 1780-1910
Paul E. Johnson Sam Patch, the Famous Jumper
Steven Hahn A Nation Under Our Feet: Black Political Struggles in the Rural South from Slavery to the Great Migration
Jeremi Suri Power and Protest: Global Revolution and the Rise of Detente
Mae Ngai Impossible Subjects: Illegal Aliens and the Making of Modern America
Louis S. Warren Buffalo Bill’s America: William Cody and the Wild West Show
Susan Scott Parish American Curiosity: Cultures of Natural History in the Colonial British Atlantic World
Charles Postel The Populist Vision
Annette Gordon-Reed The Hemingses of Monticello
Pekka Hamalainen Comanche Empire
Jackson Lears Rebirth of a Nation: The Making of Modern America, 1877-1920
Peggy Pascoe What Comes Naturally: Miscegenation Law and the Making of Race in America
Susan Carruthers Cold War Captives: Imprisonment, Escape, and Brainwashing

Taking a look at all twenty-seven books reveals some interesting characteristics. Unsurprisingly, the assigned readings are heavily weighted towards recent work:

Part of the purpose of Stanford’s core is to develop a strong working knowledge of the issues and debates of the field. For example, Charles Postel’s The Populist Vision, published in 2007, takes on interpretations advanced over the past half-century that characterize the 1890s People’s Party as quixotic and backwards-looking. Instead, Postel argues that the movement was deeply committed to ideals of modernity and progress. The Populist Vision serves as an exemplary book to assign in the graduate “core” in part because it provides a strong background for the ongoing issues, debates, and trends of how historians have interpreted late nineteenth-century American politics.

Looking at the authors themselves is also interesting. The gender breakdown is quite even, with fourteen male authors and thirteen female authors. What I decided to examine was not just who these people were, but where they received their historical training. The twenty-seven different authors received their PhD’s from only ten different schools:

Columbia University
Harvard University
Princeton University
Stanford University
University of California, Berkeley
University of California, Los Angeles
University of Helsinki
University of Leeds
University of Michigan
Yale University

In short, it’s a narrowly “elite” bunch. Eleven (over 40%) of the authors received their PhDs from Yale alone. Of the eight American schools represented, all of them currently reside in the top ten of US News and World Report’s list of history graduate programs. Of note, the authors had a more diverse background in both their undergraduate education (ranging from Montana State University to SUNY-Empire State) and the schools at which they currently taught. The prestige factor seemed to be most dominant at the graduate level.

The over-representation of elite schools highlights the stratified nature of graduate training in the American historical profession. I don’t mean to draw broad conclusions from an obviously limited and biased sample, which only reflects the decisions of three Stanford professors as to what they think are the most important recent books in the field. Yet the authors of these books were overwhelmingly trained at prestigious, “top-tier” programs. Does this mean that the products of Harvard and Yale’s programs are the only historians who received the quality training needed to write ground-breaking scholarship? Absolutely not. But the above reading list does imply that where a historian received their graduate education seems to have an outsized ripple effect on the reception and impact of their scholarship.

Topic Modeling Martha Ballard’s Diary

In A Midwife’s Tale, Laurel Ulrich describes the challenge of analyzing Martha Ballard’s exhaustive diary, which records daily entries over the course of 27 years: “The problem is not that the diary is trivial but that it introduces more stories than can be easily recovered and absorbed.” (25) This fundamental challenge is the one I’ve tried to tackle by analyzing Ballard’s diary using text mining. There are advantages and disadvantages to such an approach – computers are very good at counting the instances of the word “God,” for instance, but less effective at recognizing that “the Author of all my Mercies” should be counted as well. The question remains, how does a reader (computer or human) recognize and conceptualize the recurrent themes that run through nearly 10,000 entries?

One answer lies in topic modeling, a method of computational linguistics that attempts to find words that frequently appear together within a text and then group them into clusters. I was introduced to topic modeling through a separate collaborative project that I’ve been working on under the direction of Matthew Jockers (who also recently topic-modeled posts from Day in the Life of Digital Humanities 2010). Matt, ever-generous and enthusiastic, helped me to install MALLET (Machine Learning for LanguagE ToolkiT), developed by Andrew McCallum at UMass as “a Java-based package for statistical natural language processing, document classification, clustering, topic modeling, information extraction, and other machine learning applications to text.” MALLET allows you to feed in a series of text files, which the machine will then process and generate a user-specified number of word clusters it thinks are related topics. I don’t pretend to have a firm grasp on the inner statistical/computational plumbing of how MALLET produces these topics, but in the case of Martha Ballard’s diary, it worked. Beautifully.

With some tinkering, MALLET generated a list of thirty topics comprised of twenty words each, which I then labeled with a descriptive title. Below is a quick sample of what the program “thinks” are some of the topics in the diary:

  • MIDWIFERY: birth deld safe morn receivd calld left cleverly pm labour fine reward arivd infant expected recd shee born patient
  • CHURCH: meeting attended afternoon reverend worship foren mr famely performd vers attend public supper st service lecture discoarst administred supt
  • DEATH: day yesterday informd morn years death ye hear expired expird weak dead las past heard days drowned departed evinn
  • GARDENING: gardin sett worked clear beens corn warm planted matters cucumbers gatherd potatoes plants ou sowd door squash wed seeds
  • SHOPPING: lb made brot bot tea butter sugar carried oz chees pork candles wheat store pr beef spirit churnd flower
  • ILLNESS: unwell mr sick gave dr rainy easier care head neighbor feet relief made throat poorly takeing medisin ts stomach

When I first ran the topic modeler, I was floored. A human being would intuitively lump words like attended, reverend, and worship together based on their meanings. But MALLET is completely unconcerned with the meaning of a word (which is fortunate, given the difficulty of teaching a computer that, in this text, discoarst actually means discoursed). Instead, the program is only concerned with how the words are used in the text, and specifically what words tend to be used similarly.

Besides a remarkably impressive ability to recognize cohesive topics, MALLET also allows us to track those topics across the text. With help from Matt and using the statistical package R, I generated a matrix with each row as a separate diary entry, each column as a separate topic, and each cell as a “score” signaling the relative presence of that topic. For instance, on November 28, 1795, Ballard attended the delivery of Timothy Page’s wife. Consequently, MALLET’s score for the MIDWIFERY topic jumps up significantly on that day. In essence, topic modeling accurately recognized, in a mere 55 words (many abbreviated into a jumbled shorthand), the dominant theme of that entry:

“Clear and pleasant. I am at mr Pages, had another fitt of ye Cramp, not So Severe as that ye night past. mrss Pages illness Came on at Evng and Shee was Deliverd at 11h of a Son which waid 12 lb. I tarried all night She was Some faint a little while after Delivery.”

The power of topic modeling really emerges when we examine thematic trends across the entire diary. As a simple barometer of its effectiveness, I used one of the generated topics that I labeled COLD WEATHER, which included words such as cold, windy, chilly, snowy, and air. When its entry scores are aggregated into months of the year, it shows exactly what one would expect over the course of a typical year:

Cold Weather

As a barometer, this made me a lot more confident in MALLET’s accuracy. From there, I looked at other topics. Two topics seemed to deal largely with HOUSEWORK:

1. house work clear knit wk home wool removd washing kinds pickt helping banking chips taxes picking cleaning pikt pails

2. home clear washt baked cloaths helped washing wash girls pies cleand things room bak kitchen ironed apple seller scolt

When charted over the course of the diary, these two topics trace how frequently Ballard mentions these kinds of daily tasks:

Housework

Both topics moved in tandem, with a high correlation coefficient of 0.83, and both steadily increased as she grew older (excepting a curious divergence in the last several years of the diary). This is somewhat counter-intuitive, as one would think the household responsibilities for an aging grandmother with a large family would decrease over time. Yet this pattern bolsters the argument made by Ulrich in A Midwife’s Tale, in which she points out that the first half of the diary was “written when her family’s productive power was at its height.” (285) As her children married and moved into different households, and her own husband experienced mounting legal and financial troubles, her daily burdens around the house increased. Topic modeling allows us to quantify and visualize this pattern, a pattern not immediately visible to a human reader.

Even more significantly, topic modeling allows us a glimpse not only into Martha’s tangible world (such as weather or housework topics), but also into her abstract world. One topic in particular leaped out at me:

feel husband unwel warm feeble felt god great fatagud fatagued thro life time year dear rose famely bu good

The most descriptive label I could assign this topic would be EMOTION – a tricky and elusive concept for humans to analyze, much less computers. Yet MALLET did a largely impressive job in identifying when Ballard was discussing her emotional state. How does this topic appear over the course of the diary?

Emotion

Like the housework topic, there is a broad increase over time. In this chart, the sharp changes are quite revealing. In particular, we see Martha more than double her use of EMOTION words between 1803 and 1804. What exactly was going on in her life at this time? Quite a bit. Her husband was imprisoned for debt and her son was indicted by a grand jury for fraud, causing a cascade effect on Martha’s own life – all of which Ulrich describes as “the family tumults of 1804-1805.” (285) Little wonder that Ballard increasingly invoked “God” or felt “fatagued” during this period.

I am absolutely intrigued by the potential for topic modeling in historic source material. In many ways, it seems that Martha Ballard’s diary is ideally suited for this kind of analysis. Short, content-driven entries that usually touch upon a limited number of topics appear to produce remarkably cohesive and accurate topics. In some cases (especially in the case of the EMOTION topic), MALLET did a better job of grouping words than a human reader. But the biggest advantage lies in its ability to extract unseen patterns in word usage. For instance, I would not have thought that the words “informed” or “hear” would cluster so strongly into the DEATH topic. But they do, and not only that, they do so more strongly within that topic than the words dead, expired, or departed. This speaks volumes about the spread of information – in Martha Ballard’s diary, death is largely written about in the context of news being disseminated through face-to-face interactions. When used in conjunction with traditional close reading of the diary and other forms of text mining (for instance, charting Ballard’s social network), topic modeling offers a new and valuable way of interpreting the source material.

I’ll end my post with a topic near and dear to Martha Ballard’s heart: her garden. To a greater degree than any other topic, GARDENING words boast incredible thematic cohesion (gardin sett worked clear beens corn warm planted matters cucumbers gatherd potatoes plants ou sowd door squash wed seeds) and over the course of the diary’s average year they also beautifully depict the fingerprint of Maine’s seasonal cycles:

Gardening


Note: this post is part of an ongoing series detailing my work on text mining Martha Ballard’s diary.

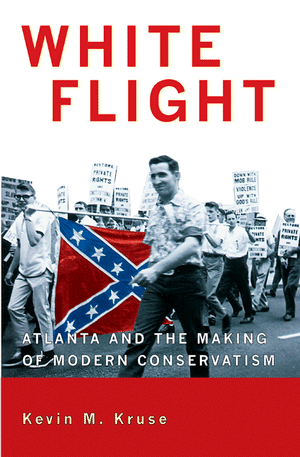
Review: White Flight: Atlanta and The Making of Modern Conservatism

By 1970, the north Atlanta suburban counties of Gwinnett, Cobb, and north Fulton had experienced massive explosions in both population and median income. Their racial profiles were also 95, 96, and 99 percent white, respectively (245). In White Flight: Atlanta and the Making of Modern Conservatism, Kevin Kruse explores the processes leading up to this shift. Kruse sets his study within Atlanta’s urban landscape during the 1950s and 1960s and traces the gradual abandonment of spaces by white citizens and its political impact on the development of the conservative movement. By charting three distinct stages of the movement, Kruse reveals a gradual reorientation in political patterns of white resistance, as white Atlantans moved towards a coded ideological emphasis on individual rights, privatization, and small government. Kruse argues that this combination of physical relocation and political consolidation proved to be the most successful strategy employed by those resisting the civil rights movement.

By the late 1940s and early 1950s, working-class whites felt themselves under siege from what they saw as a black invasion of their neighborhoods and public spaces such as parks and swimming pools. Working-class whites at first turned to organized violence and intimidation, but soon realized the importance of winning the battle for public image. In Kruse’s words, “In time, they would learn to put aside the brown shirts of the [white supremacist] Columbians and the white sheets of the Klan and instead present themselves as simple homeowners and concerned citizens.” (44) On an ideological level, they moved from trying to protect the integrity of their communities (a cohesion that Kruse convincingly undermines), and instead began to emphasize their individual rights and liberties to live amongst whomever they chose. In many neighborhoods, their struggle was not enough, as the first wave of black homeowners caused a stampede of white individuals rushing to sell their homes before property values decreased.

Meanwhile, a similar battle over the desegregation of public schools led middle-class whites into the fray during the 1950s. Segregationist leaders quickly picked up on a central theme that ran through their movement (and one that runs through White Flight as well): “freedom of association.” For a middle-class white father, barring blacks from attending the same school as his daughter was purportedly less about denying black people rights as it was preserving his own right to determine who his daughter could and should interact with. Even as this line of reasoning proved ineffectual at halting desegregation, white families fled from public schools into private ones, creating a second-wave of de facto segregation in Atlanta’s school system.

The third stage of white flight came in the early 1960s. As working and middle-class whites faced the integration of their neighborhoods, parks, and schools, many upper-class whites observed the conflict form a distance, safely ensconced in their wealthy neighborhoods, country clubs, and private schools. But with the passage of the Civil Rights Act, suddenly their businesses came under direct assault. Elite businessman, hitherto allied in a moderate coalition with white politicians and black leaders, bitterly struggled against organized sit-in protests and later government injunctions that aimed to desegregate their restaurants and department stores. It was during their struggle that the earlier shifts towards individual rights and privatization crystallized into an organized and increasingly powerful conservative ideology.

The strength of Kruse’s argument lies in tracing this conservative political crystallization, sometimes at the expense of a more rigorous analysis of white flight as a spatial phenomenon. While maps are scattered throughout White Flight, most of them serve as modest visual signposts, when they have the potential to more deeply enrich the project. Nevertheless, Kruse persuasively argues that this tandem of political and spatial movements had profound historical implications. As white Americans increasingly coalesced into white suburban (and later exurban) enclaves, they eventually became the backbone of the Republican party. This “politics of suburban secession,” maintained the traditional tenets of white flight: retreating from any and all interaction with the black community (now synonymous the city itself) and championing minimal government, headlong privatization, and the primacy of the individual.

Kruse is an adept narrator, weaving together a host of characters and events into a compelling storyline of the racial landscape of Atlanta during the mid-20th century. He paints a convincing portrait of a coalescing conservative movement based on withdrawal and charts the distinctive class divisions within this movement. The reader is sometimes left wishing for the kind of broader analysis that mainly occupies the final chapter and epilogue of his book. Atlanta’s patterns of white flight were simultaneously taking place in spaces across the country, yet Kruse offers only passing glimpses of how the city fit within a national framework. Despite this, White Flight remains a compelling case study on the origins of the modern conservative movement within the social and political backlash against the civil rights movement.


Kevin M. Kruse, White Flight: Atlanta and the Making of Modern Conservatism (Princeton University Press, 2005).

Chasing the “Perfect Data” Dragon

Whenever I put on my proselytizing robes to explain the potential of digital humanities to a layperson, I usually point towards the usual data deluge trope. “If you read a book a day for the rest of your life, it would take you 30-something lifetimes to read one million books. Google has already digitized several times that number.” etc. etc. The picture I end up painting is one where the DH community is better-positioned than traditional academics to access, manipulate, and draw out meaning from the growing mountains of digital data. Basically, now that all this information is digitized, we can feed the 1’s and 0’s into a machine and, presto, innovative scholarship.

Of course, my proselytizing is a bit disingenuous. The dirty little secret is that not all data is created equal. And especially within the humanist’s turf, most digitized sources are rarely “machine-ready”. The more projects I work on, the more and more convinced I become that there is one real constant to them: I always spend far more time than I expect preparing, cleaning, and improving my data. Why? Because I can.

A crucial advantage to digital information is that it’s dynamic and malleable. You can clean up a book’s XML tags, or tweak the coordinates of a georectified map, or expand the shorthand abbreviations in a digitized letter. Which is all well and good, but comes with a pricetag. In a way that is fundamentally different from the analog world, perfection is theoretically attainable. And that’s where an addictive element creeps into the picture. When you can see mistakes and know you can fix them, the temptation to both find and fix every single one is overwhelming.

In many respects, cleaning your data is absolutely crucial to good scholarship. The historian reading an 18th-century newspaper might know that “Gorge Washington” refers to the first president of the United States, but unless the spelling error gets fixed, that name probably won’t get identified correctly by a computer. Of course, it’s relatively easy to change “Gorge” to “George”, but what happens when you are working with 30,000 newspaper pages? Manually going through and fixing spelling mistakes (or, more likely, OCR mistakes) defeats the purpose and neuters the advantage of large-scale text mining. While there are ways to automate this kind of data cleaning, most methods are going to be surprisingly time-intensive. And once you start down the path of data cleaning, it can turn into whack-a-mole, with five “Thoms Jefferson”s poking their heads up out of the hole for every one “Gorge Washington” you fix.

Chasing the “perfect data” dragon becomes an addictive cycle, one fueled by equal parts optimism and fear. Having a set of flawlessly-encoded Gothic novels could very well lead to the next big breakthrough in genre classification. On the other hand, what if all those missed “Gorge Washingtons” are the final puzzle pieces that will illuminate early popular conceptions of presidential power? The problem is compounded by the fact that, in many cases, the specific errors can be fixed. But in breathlessly attempting to meet the “data deluge” problem, the number and kind of specific errors get multiplied by several orders of magnitude over increasingly larger and larger bodies of information and material – which severely complicates the ability to both locate and rectify all of them.

At some point, the digital material has to simply be “good enough”. But breaking out of the “perfect data” dragon-chasing is easier said than done. “How accurate does my dataset have to be to in order to be statistically relevant?” “How do I even know how clean my data actually is?” “How many hours of my time is it worth to bump up the data accuracy from 96% to 98%?” These are the kinds of questions that DH researchers suddenly struggle with – questions that a background in the humanities ill-prepares them to answer. Just like so many aspects of doing this kind of work, there is a lot to learn from other disciplines.

Certain kinds of data quality issues get mitigated by the “safety in numbers” approach. Pinpointing the exact cross-streets of a rail depot is pretty important if you’re creating a map of a small city. But if you’re looking at all the rail depots in, say, the Midwest, the “good enough” degree of locational error gets substantially bigger. Over the course of thirty million words, the number of “George Washingtons” are going to far outweigh and balance out the number of “Gorge Washingtons”. With large-scale digital projects, it’s easier to see that chasing the “perfect data” dragon is both impossible and unnecessary. On the other hand, certain kinds of data quality problems get magnified with a larger scale. Small discrepancies get flattened out with bigger datasets. But foundational or commonly-repeated errors get exaggerated with a larger dataset, particularly if some errors have been fixed and others not. For instance, if you fixed every “Gorge Washington” but didn’t catch the more frequently misspelled “Thoms Jefferson”, comparing the textual appearances of the two presidents over those thirty million words is going to be heavily skewed in George’s direction.

As non-humanities scholars have been demonstrating for years, these problems aren’t new and they aren’t unmanageable. But as digital humanists sort through larger and larger sets of data, it will become increasingly important to know when to ignore the dragon and when to give chase.